
Project 03 / 06
Reinforcement Learning Thermostat Controller Comparison
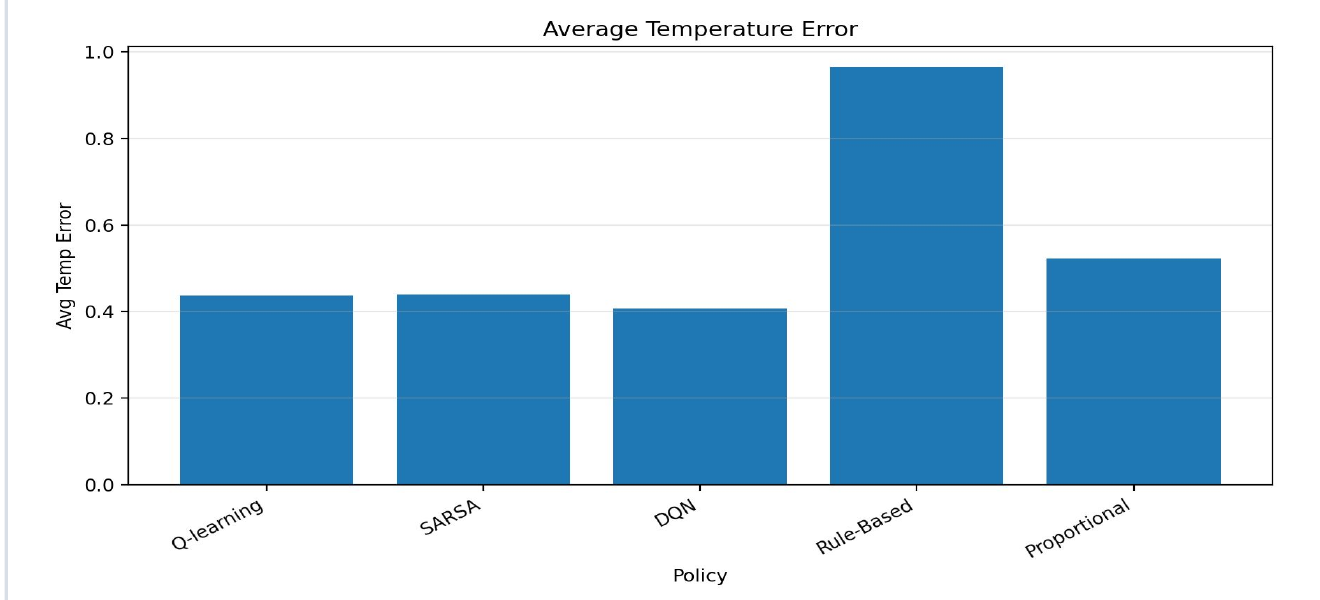
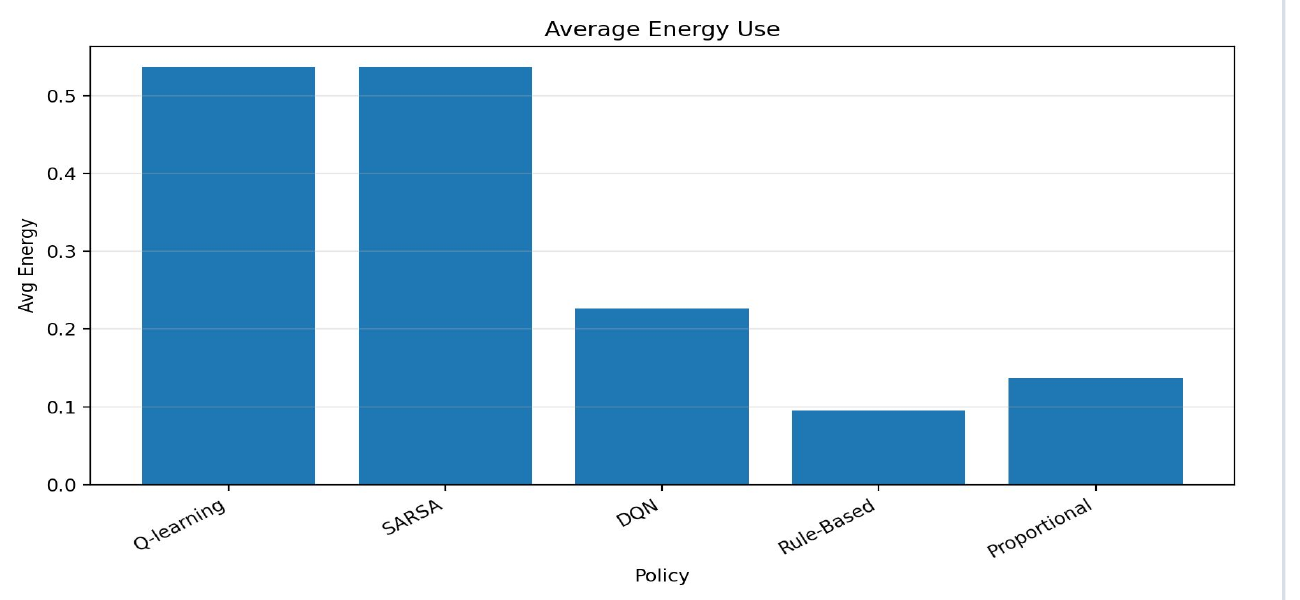
Simulated thermal-control study comparing Q-learning, SARSA, DQN, rule-based, and proportional thermostat controllers under matched conditions for temperature error, normalized control effort, reward, and action switching.
Representative response and evaluation-wide switching
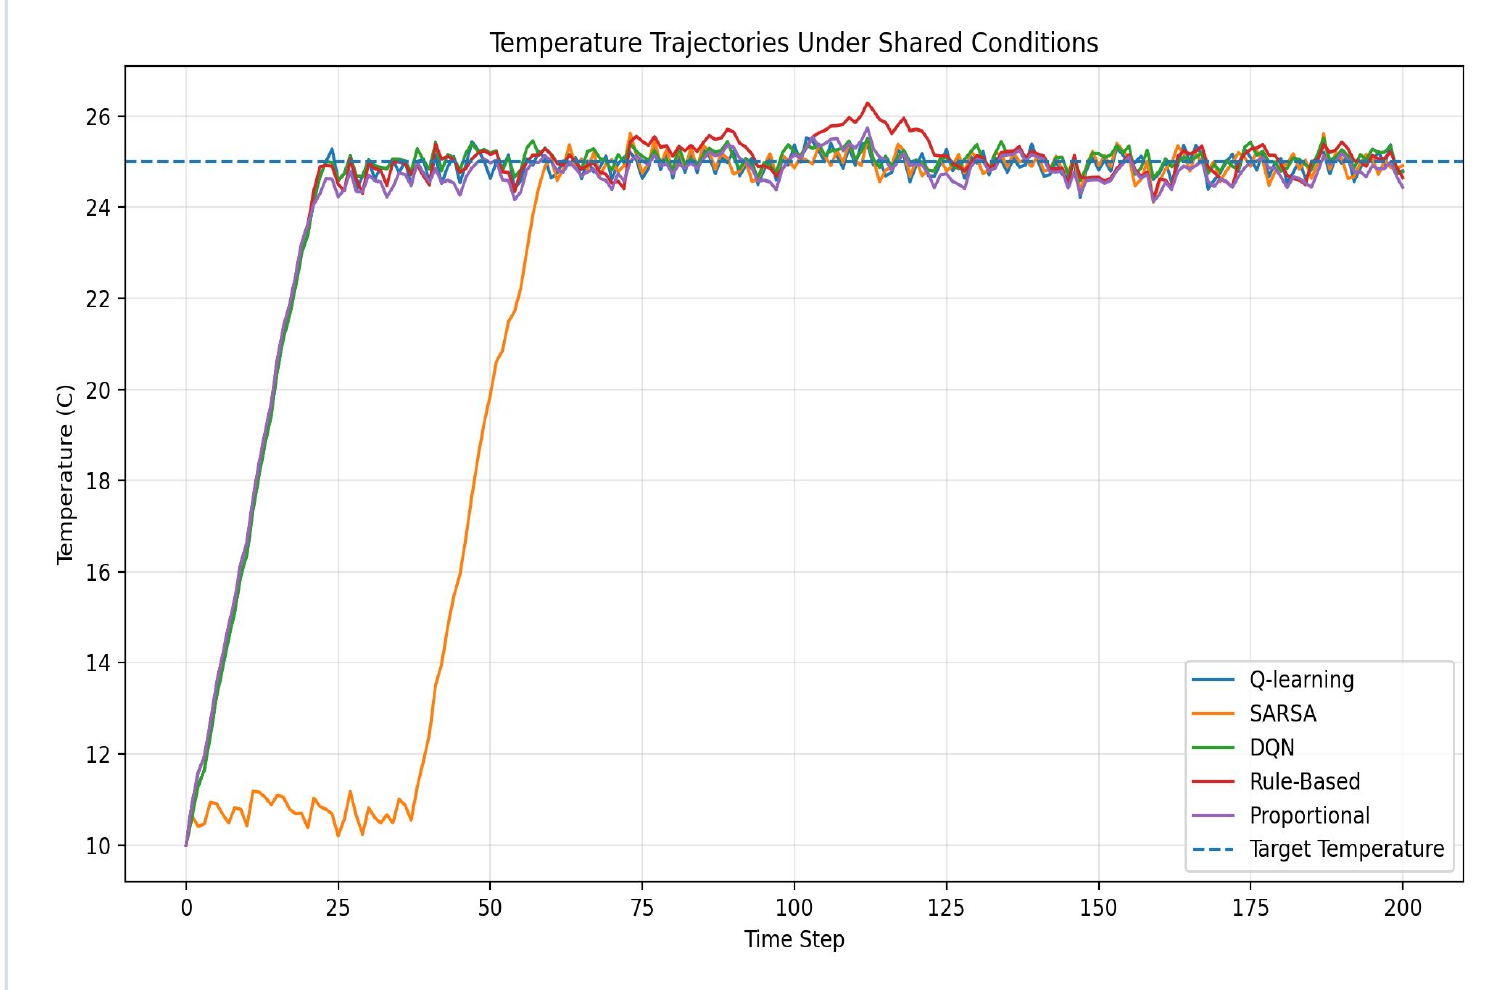
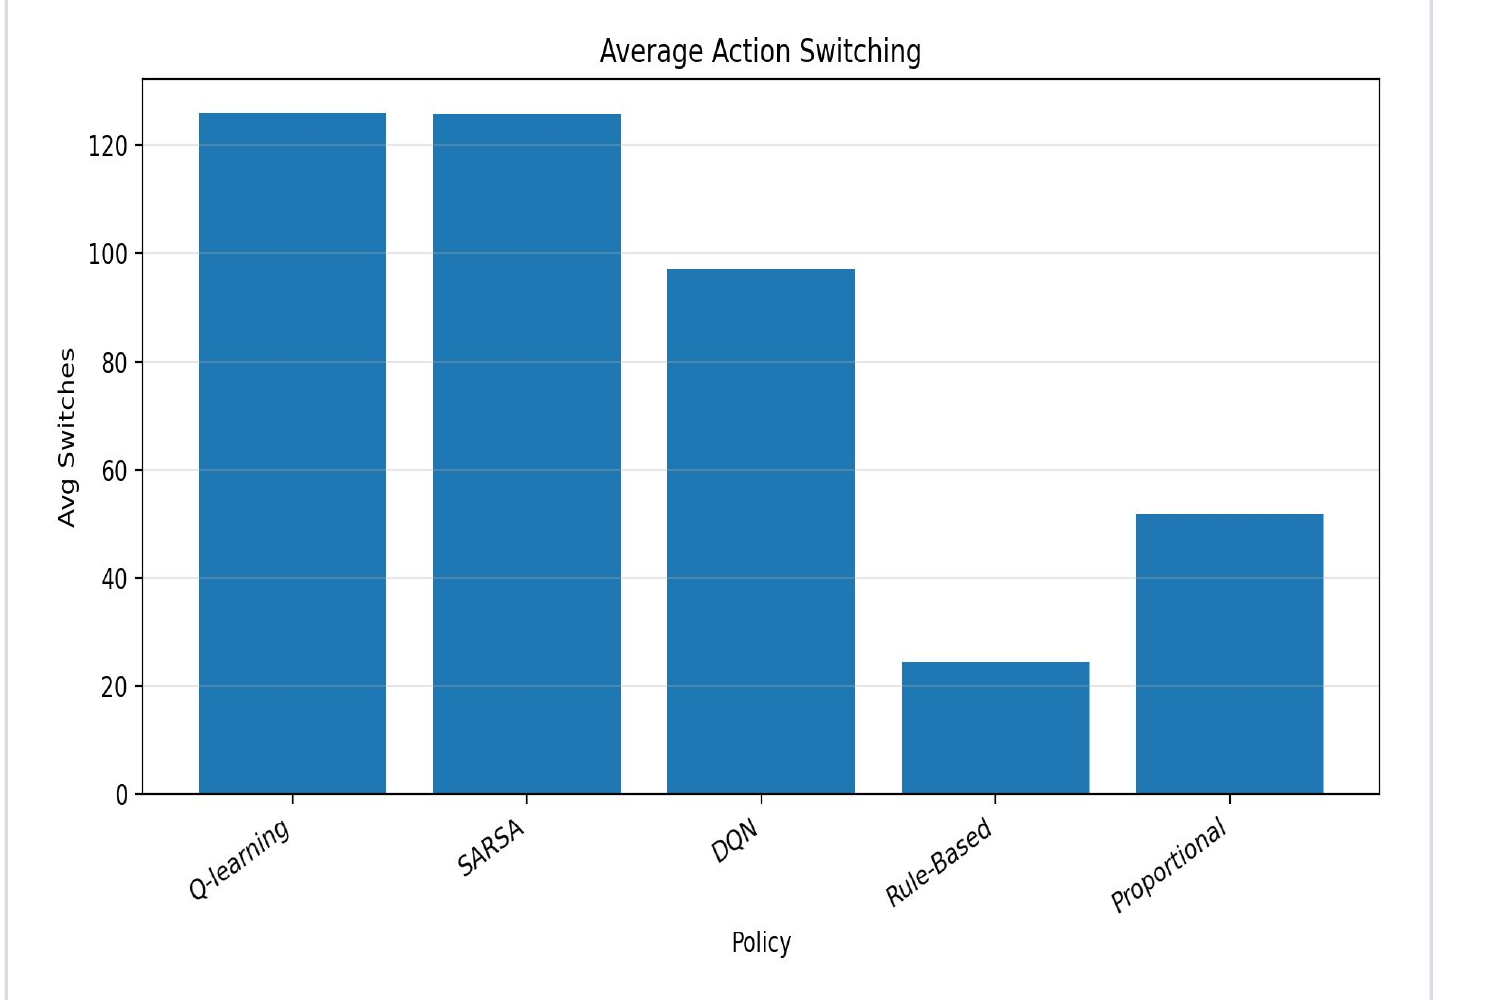
Across 100 matched simulated evaluations, DQN recorded the highest mean reward (-86.05) and lowest mean temperature error (0.408°C) under the documented reward, but the learned controllers averaged 97.13–126.00 action changes per 200-step episode versus 24.33–51.81 for the two traditional baselines.
01 — A controlled thermostat comparison
Multiple thermostat policies are evaluated in one standardized simulation so tracking, control effort, reward, and switching can be compared on common terms.